python2处理word pythonword文件处理
- 作者: 黄某某007
- 来源: 51数据库
- 2020-04-20
#-*- encoding: utf8 -*-
import win32com
from win32com.client import Dispatch, constants
import win32com.client
import __main__
import os
import new
import sys
import re
import string
reload(sys)
sys.setdefaultencoding('utf8')
#from fileinput import filename
class Word(object):
#初始化word对象
def __init__(self, uri):
self.objectword(uri)
#创建word对象
def objectword(self,url):
self.word = win32com.client.Dispatch('Word.Application')
self.word.Visible = 0
self.word.DisplayAlerts = 0
self.docx = self.word.Documents.Open(url)
self.wrange = self.docx.Range(0, 0)
#关闭word
def close(self):
self.word.Documents.Close()
self.word.Quit()
#创建word
def create(self):
pass
#在word中进行查找
def findword(self, key):
question = []
uri = r'E:\XE\ctb.docx'
self.objectword(uri)
#读取所有的word文档内容
range = self.docx.Range(self.docx.Content.Start,self.docx.Content.End)
question = str(range).split("&")
#查找内容
#question = re.split(r"(\r[1][0-9][0-9]+.)",str(range))
#l = question[0].split("\d+.")
for questionLine in question:
questionLine = questionLine.strip('\n')
l = re.split(r"([1][0-9][0-9]+.)",questionLine)
del l[0]
for t in l:
s = str(key[0:3])
if str(t).find(s) > -1:
#插入
g = string.join(l)
print g.encode('gb2312')
#print g.decode("")
self.insertword(g)
print "sss"
else:
print "ttt"
#插入word
def insertword(self,w):
url = r'E:\XE\ctb.doc'
self.objectword(url)
self.wrange.InsertAfter(w)
pass
#读取数据源
def source(self, src):
f = open(src)
d = f.readlines()
for l in d:
name, question01, question02, question03, question04, question05 = tuple(l.decode('utf8').split('\t'))
if question01 != u'全对':
#self.wrange.InsertAfter(name)
self.findword(question01)
return self
Word(r'E:\XE\xx.docx').source(r'E:\XE\xe.txt').close()
求写一段python处理word文件的批处理命令。
python支持使用com技术调用word,但是不能直接操纵word文件,因为word文件是私有格式。所以你说的正则表达式查找替换,如果word本身不支持,那就没有办法了
python gensim怎么用word2vect
词向量(word2vec)原始的代码是C写的,python也有对应的版本,被集成在一个非常牛逼的框架gensim中。
我在自己的开源语义网络项目graph-mind(其实是我自己写的小玩具)中使用了这些功能,大家可以直接用我在上面做的进一步的封装傻瓜式地完成一些操作,下面分享调用方法和一些code上的心得。
1.一些类成员变量:
[python]view plaincopy
def__init__(self,modelPath,_size=100,_window=5,_minCount=1,_workers=multiprocessing.cpu_count()):
self.modelPath=modelPath
self._size=_size
self._window=_window
self._minCount=_minCount
self._workers=_workers
definitTrainWord2VecModel(self,corpusFilePath,safe_model=False):
'''''
initandtrainaneww2vmodel
(corpusFilePathcanbeapathofcorpusfileordirectoryorafiledirectly,insometimeitcanbesentencesdirectly
aboutsoft_model:
ifsafe_modelistrue,theprocessoftrainingusesupdatewaytorefreshmodel,
andthiscankeeptheusageofos'smemorysafebutslowly.
andifsafe_modelisfalse,theprocessoftrainingusesthewaythatloadall
corpuslinesintoasentenceslistandtrainthemonetime.)
'''
extraSegOpt().reLoadEncoding()
fileType=localFileOptUnit.checkFileState(corpusFilePath)
iffileType==u'error':
warnings.warn('loadfileerror!')
returnNone
else:
model=None
iffileType==u'opened':
print('trainingmodelfromsingleFile!')
model=Word2Vec(LineSentence(corpusFilePath),size=self._size,window=self._window,min_count=self._minCount,workers=self._workers)
eliffileType==u'file':
corpusFile=open(corpusFilePath,u'r')
print('trainingmodelfromsingleFile!')
model=Word2Vec(LineSentence(corpusFile),size=self._size,window=self._window,min_count=self._minCount,workers=self._workers)
eliffileType==u'directory':
corpusFiles=localFileOptUnit.listAllFileInDirectory(corpusFilePath)
print('trainingmodelfromlistFilesofdirectory!')
ifsafe_model==True:
model=Word2Vec(LineSentence(corpusFiles[0]),size=self._size,window=self._window,min_count=self._minCount,workers=self._workers)
forfileincorpusFiles[1:len(corpusFiles)]:
model=self.updateW2VModelUnit(model,file)
else:
sentences=self.loadSetencesFromFiles(corpusFiles)
model=Word2Vec(sentences,size=self._size,window=self._window,min_count=self._minCount,workers=self._workers)
eliffileType==u'other':
#TODOaddsentenceslistdirectly
pass
model.save(self.modelPath)
model.init_sims()
print('producingword2vecmodel...ok!')
returnmodel
model=Word2Vec(LineSentence(corpusFilePath),size=self._size,window=self._window,min_count=self._minCount,workers=self._workers)
defupdateW2VModelUnit(self,model,corpusSingleFilePath):
'''''
(onlycanbeasingleFile)
'''
fileType=localFileOptUnit.checkFileState(corpusSingleFilePath)
iffileType==u'directory':
warnings.warn('cannotdealadirectory!')
returnmodel
iffileType==u'opened':
trainedWordCount=model.train(LineSentence(corpusSingleFilePath))
print('updatemodel,updatewordsnumis:'+trainedWordCount)
eliffileType==u'file':
corpusSingleFile=open(corpusSingleFilePath,u'r')
trainedWordCount=model.train(LineSentence(corpusSingleFile))
print('updatemodel,updatewordsnumis:'+trainedWordCount)
else:
#TODOaddsentenceslistdirectly(sameaslastfunction)
pass
returnmodel
deffinishTrainModel(self,modelFilePath=None):
'''''
warning:afterthis,themodelisread-only(can'tbeupdate)
'''
ifmodelFilePath==None:
modelFilePath=self.modelPath
model=self.loadModelfromFile(modelFilePath)
model.init_sims(replace=True)
defgetWordVec(self,model,wordStr):
'''''
gettheword'svectorasarrayListtypefromw2vmodel
'''
returnmodel[wordStr]
defqueryMostSimilarWordVec(self,model,wordStr,topN=20):
'''''
MSimilarwordsbasicqueryfunction
return2-dimList[0]isword[1]isdouble-prob
'''
similarPairList=model.most_similar(wordStr.decode('utf-8'),topn=topN)
returnsimilarPairList
defculSimBtwWordVecs(self,model,wordStr1,wordStr2):
'''''
twowordssimilarbasicqueryfunction
returndouble-prob
'''
similarValue=model.similarity(wordStr1.decode('utf-8'),wordStr2.decode('utf-8'))
returnsimilarValue
defqueryMSimilarVecswithPosNeg(self,model,posWordStrList,negWordStrList,topN=20):
'''''
pos-negMSimilarwordsbasicqueryfunction
return2-dimList[0]isword[1]isdouble-prob
'''
posWordList=[]
negWordList=[]
forwordStrinposWordStrList:
posWordList.append(wordStr.decode('utf-8'))
forwordStrinnegWordStrList:
negWordList.append(wordStr.decode('utf-8'))
pnSimilarPairList=model.most_similar(positive=posWordList,negative=negWordList,topn=topN)
returnpnSimilarPairList
defcopeMSimilarVecsbtwWordLists(self,model,wordStrList1,wordStrList2,topN_rev=20,topN=20):
'''''
rangewordvecresfortwowordListfromsourcetotarget
usewordVectortoexpresstherelationshipbetweensrc-wordListandtag-wordList
first,usethetag-wordListasneg-wordListtogettherev-wordList,
thenusethescr-wordListandtherev-wordListasthenewsrc-tag-wordList
topN_revistopNofrev-wordListandtopNisthefinaltopNofrelationshipvec
'''
srcWordList=[]
tagWordList=[]
srcWordList.extend(wordStr.decode('utf-8')forwordStrinwordStrList1)
tagWordList.extend(wordStr.decode('utf-8')forwordStrinwordStrList2)
revSimilarPairList=self.queryMSimilarVecswithPosNeg(model,[],tagWordList,topN_rev)
revWordList=[]
revWordList.extend(pair[0].decode('utf-8')forpairinrevSimilarPairList)
stSimilarPairList=self.queryMSimilarVecswithPosNeg(model,srcWordList,revWordList,topN)
returnstSimilarPairList
modelPath是word2vec训练模型的磁盘存储文件(model在内存中总是不踏实),_size是词向量的维度,_window是词向量训练时的上下文扫描窗口大小,后面那个不知道,按默认来,_workers是训练的进程数(需要更精准的解释,请指正),默认是当前运行机器的处理器核数。这些参数先记住就可以了。
2.初始化并首次训练word2vec模型
完成这个功能的核心函数是initTrainWord2VecModel,传入两个参数:corpusFilePath和safe_model,分别代表训练语料的路径和是否选择“安全模式”进行初次训练。关于这个“安全模式”后面会讲,先看代码:
[python]view plaincopy
首先是一些杂七杂八的,判断一下输入文件路径下访问结果的类型,根据不同的类型做出不同的文件处理反应,这个大家应该能看懂,以corpusFilePath为一个已经打开的file对象为例,创建word2vec model的代码为:
[python]view plaincopy
其实就是这么简单,但是为了代码健壮一些,就变成了上面那么长。问题是在面对一个路径下的许多训练文档且数目巨大的时候,一次性载入内存可能不太靠谱了(没有细研究gensim在Word2Vec构造方法中有没有考虑这个问题,只是一种习惯性的警惕),于是我设定了一个参数safe_model用于判断初始训练是否开启“安全模式”,所谓安全模式,就是最初只载入一篇语料的内容,后面的初始训练文档通过增量式学习的方式,更新到原先的model中。
上面的代码里,corpusFilePath可以传入一个已经打开的file对象,或是一个单个文件的地址,或一个文件夹的路径,通过函数checkFileState已经做了类型的判断。另外一个函数是updateW2VModelUnit,用于增量式训练更新w2v的model,下面会具体介绍。loadSetencesFromFiles函数用于载入一个文件夹中全部语料的所有句子,这个在源代码里有,很简单,哥就不多说了。
3.增量式训练更新word2vec模型
增量式训练w2v模型,上面提到了一个这么做的原因:避免把全部的训练语料一次性载入到内存中。另一个原因是为了应对语料随时增加的情况。gensim当然给出了这样的solution,调用如下:
[python]view plaincopy
简单检查文件type之后,调用model对象的train方法就可以实现对model的更新,这个方法传入的是新语料的sentences,会返回模型中新增词汇的数量。函数全部执行完后,return更新后的model,源代码中在这个函数下面有能够处理多类文件参数(同2)的增强方法,这里就不多介绍了。
4.各种基础查询
当你确定model已经训练完成,不会再更新的时候,可以对model进行锁定,并且据说是预载了相似度矩阵能够提高后面的查询速度,但是你的model从此以后就read only了。
[python]view plaincopy
可以看到,所谓的锁定模型方法,就是init_sims,并且把里面的replace参数设定为True。
然后是一些word2vec模型的查询方法:
[python]view plaincopy
[python]view plaincopy
[python]view plaincopy
上述方法都很简单,基本上一行解决,在源代码中,各个函数下面依然是配套了相应的model文件处理版的函数。其中,getWordVec是得到查询词的word2vec词向量本身,打印出来是一个纯数字的array;queryMostSimilarWordVec是得到与查询词关联度最高的N个词以及对应的相似度,返回是一个二维list(注释里面写的蛮清楚);culSimBtwWordVecs是得到两个给定词的相似度值,直接返回double值。
5.Word2Vec词向量的计算
研究过w2v理论的童鞋肯定知道词向量是可以做加减计算的,基于这个性质,gensim给出了相应的方法,调用如下:
[python]view plaincopy
由于用的是py27,所以之前对传入的词列表数据进行编码过滤,这里面posWordList可以认为是对结果产生正能量的词集,negWordList则是对结果产生负能量的词集,同时送入most_similar方法,在设定return答案的topN,得到的返回结果形式同4中的queryMostSimilarWordVec函数,大家可以这样数学地理解这个操作:
下面一个操作是我自创的,假设我想用上面词向量topN“词-关联度”的形式展现两个词或两组词之间的关联,我是这么做的:
[python]view plaincopy
这个操作的思路就是,首先用两组词中的一组作为negWordList,传入上面的queryMSimilarVecswithPosNeg函数,得到topN一组的中转词,在使用这些中转词与原先的另一组词进行queryMSimilarVecswithPosNeg操作,很容易理解,第一步得到的是一组词作为negWordList的反向结果,再通过这个反向结果与另一组词得到“负负得正”的效果。这样就可以通过一组topN的“词-关联度”配对List表示两组词之间的关系。
python处理word文档
有个库叫『Python-docx』
安装之后 python 可以读写 word 文档,就可以拼接了。更多
你好,我是用了这个库,下面是代码res是查询到的要写入文档的内容,这个内容包括普通段落和表格,下面的代码运行完之后,new.docx中只有最后一次的内容,并没有循环写入(for循环执行了),请问这是什么问题,谢谢
for k2v in k2v_all :
res = data_handler.query_files(file_ids=file_id, download=1, request=req)
with open("new.docx", 'ab') as fd:
fd.write(res.content)
因为你写放在了 for 循环里面,你的代码相当于:
按行读取:
清空 word,并将这一行写入 word。
所以就只有最后一段了。
应该是:
withopen("new.docx","ab")asfd:forxiny:
fd.write(x)
withopen("new.docx","ab+")asfd:
for k2v in k2v_all :
res = data_handler.query_files(file_ids=file_id, download=1, request=req)
fd.write(res.content)
再问一下,这是我修改后的代码,执行完后,word文档就打不开了,显示 内容有问题,有无法读取的内容。res.content的内容应该是没问题的,如果不是追加,只是写文档,内容是可以加进去的
python操作word文档,如何合并单元格
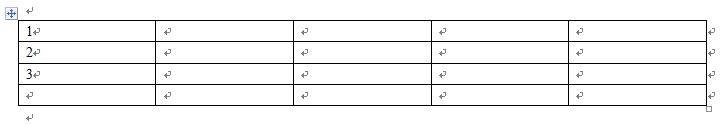
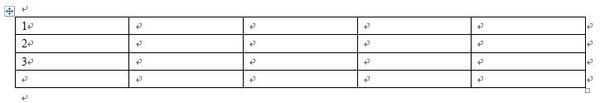
>>>app=my.Office.Word.GetInstance()>>>doc=app.Documents[0]
>>>table=doc.Tables[1]
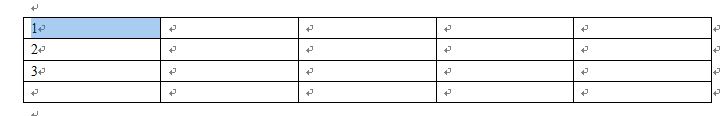
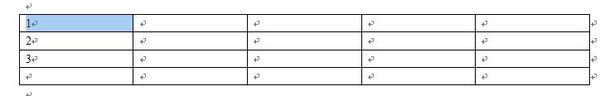
>>>table.Cell(1,1).Select()
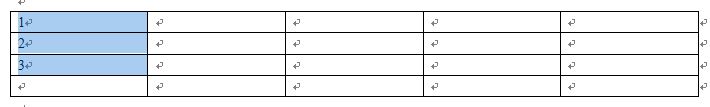
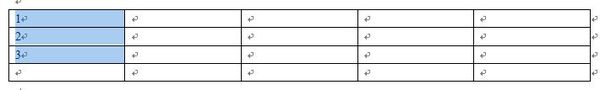
>>>app.Selection.MoveDown(Unit=5,Count=2,Extend=1)
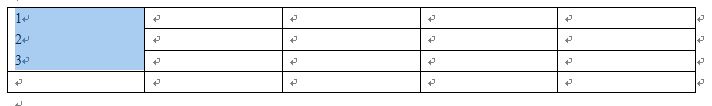
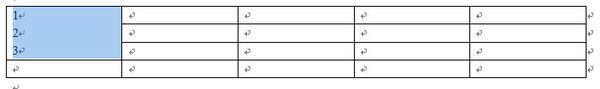
>>>app.Selection.Cells.Merge()
>>>
my.Office.Word.GetInstance()用win32com得到Word的Application对象的实例
我所使用的样本word文件中包含两个Table第二个Table是想要修改的
table.Cell(1,1).Select()用于选中这个样表的第一个单元格
app.Selection.MoveDown用于获得向下多选取3个单元格
app.Selection.Cells.Merge()用于执行合并工作
python如何获取word文件中某个关键字之后的表格
最好是全部都读取到程序中,在程序中进行判断。
本文实例讲述了Python实现批量读取word中表格信息的方法。分享给大家供大家参考。具体如下:
单位收集了很多word格式的调查表,领导需要收集表单里的信息,我就把所有调查表放一个文件里,写了个python小程序把所需的信息打印出来
#coding:utf-8
import os
import win32com
from win32com.client import Dispatch, constants
from docx import Document
def parse_doc(f):
"""读取doc,返回姓名和行业
"""
doc = w.Documents.Open( FileName = f )
t = doc.Tables[0] # 根据文件中的图表选择信息
name = t.Rows[0].Cells[1].Range.Text
situation = t.Rows[0].Cells[5].Range.Text
people = t.Rows[1].Cells[1].Range.Text
title = t.Rows[1].Cells[3].Range.Text
print name, situation, people,title
doc.Close()
def parse_docx(f):
"""读取docx,返回姓名和行业
"""
d = Document(f)
t = d.tables[0]
name = t.cell(0,1).text
situation = t.cell(0,8).text
people = t.cell(1,2).text
title = t.cell(1,8).text
print name, situation, people,title
if __name__ == "__main__":
w = win32com.client.Dispatch('Word.Application')
# 遍历文件
PATH = "H:\work\\aaa" # windows文件路径
doc_files = os.listdir(PATH)
for doc in doc_files:
if os.path.splitext(doc)[1] == '.docx':
try:
parse_docx(PATH+'\\'+doc)
except Exception as e:
print e
elif os.path.splitext(doc)[1] == '.doc':
try:
parse_doc(PATH+'\\'+doc)
except Exception as e:
print e
希望本文所述对大家的Python程序设计有所帮助。
如何用python读取word
使用Python的内部方法open()读取文本文件
try:f=open('/file','r')
print(f.read())
finally:
iff:
f.close()
如果读取word文档推荐使用第三方插件,python-docx 可以在官网上下载
使用方式
#-*-coding:cp936-*-importdocx
document=docx.Document(文件路径)
docText='\n\n'.join([
paragraph.text.encode('utf-8')forparagraphindocument.paragraphs
])
printdocText
如何把pdf文件转换成word文件 Python文件处理之文件指针
对于不允许做修改的PDF文件——就是加密加了权限的PDF,首先要去除密码或者去除数字证书,推荐用PDF Password Remove,然后再按照下面的方法进行转换为word文件:
方法一:用软件PDF To Word Converter,使用之后然后有两种结果
1、转化出来的就是想要的word,这种情况最理想了;
2、转化出来的word上都是图片,需要上网找“ABBYY finereader v9”一类的文字识别软件。ABBYY finereader v9是我见过的最强大的PDF(图片格式或者是扫描件)转word的软件。它是一款OCR软件,界面比较简洁明,9.0和以上版本有简体中文版的,支持100语言的识别,特别是混合多种语言识别效果也非常好:安装完毕之后,首先把图片上的文字识别出来,然后再对照图片把识别错误的地方改过来,这样就实现了,从JPEG文件到word的格式转换。
方法二:在线PDF转Word共有以下几个步骤:
• 点击浏览按钮选择需要转换的PDF文件。
• 输入需要转换的页码,以逗号分割开,如果转换所有的页面可以跳过这一步。
• 点击按钮上传文件,然后等着就可以了。
• 点击下载链接把做好的文件下载到本地就可以了;
方法三:用其他软件Wondershare PDFelement等处理。
转载请注明出处51数据库 » python2处理word pythonword文件处理